Lecture: Nonconvex Optimization for Deep Learning (ML-4311)
University of Tübingen, Wintersemester 2026/2027
Dr. Antonio Orvieto, ELLIS Principal Investigator at MPI.
Time/Date
The lecture is from 2 to 4 pm on Monday, followed by exercise/presentations from 4 to 5 pm (both in the lecture hall at Maria-von-Linden-Str. 6).
Exercise Sessions may (let's decide!) include student presentations, and they start in the third week.
Attending the lecture in person is advised, but I will try to record each session.
Material
All materials can be found at https://drive.google.com/drive/folders/1ZasVKDEM02UiLAOviv9eZy8wROB9l0ck
TLDR;
Take this module if
- You know what deep learning is, and that deep models are trained with variants of SGD;
- You are curious to understand what influences training speed and generalization in vision and language models.
- Want to know about recent topics such as the NTK, edge of stability, maximum-update parametrization (muP), and Muon.
- You like maths and want to know more about deep learning theory.
Registration
Register on ILIAS, so you can get email updates (e.g., grades, canceled lectures).
Contact
For communication purposes, please use only my ELLIS email: antonio@tue.ellis.eu
Basic Information
Note: This lecture does not overlap with "Convex and Nonconvex Optimization." While students are encouraged to take "Convex and Nonconvex Optimization" to solidify their understanding of SGD and basic optimization concepts (duality, interior point methods, constraints), we will only discuss optimization in the context of training deep neural networks and often drift into discussions regarding model design and initialization.
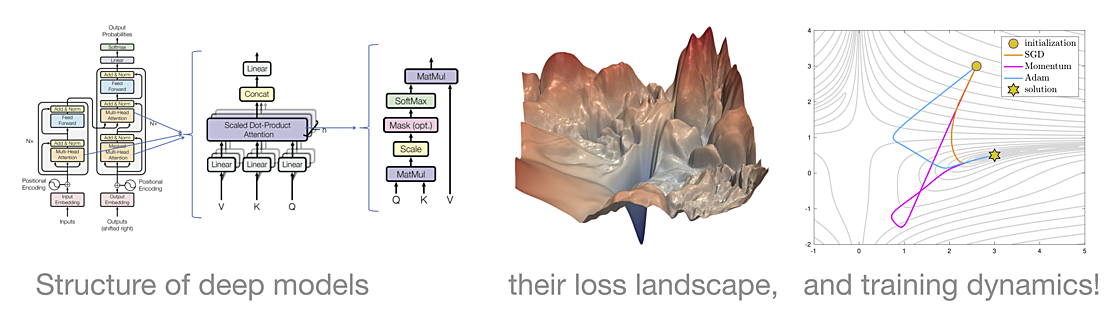
Successful training of deep learning models requires non-trivial optimization techniques. This course gives a formal introduction to the field of nonconvex optimization through the study of neural network training, with particular emphasis on modern large models and LLMs. We will start with a recap of essential optimization concepts and then proceed to convergence analysis of SGD in the general nonconvex smooth setting. Here, we will explain why standard worst-case nonconvex optimization theory cannot fully explain the successful training of neural networks. After discussing the properties of stationary points (e.g., saddle points and local minima), we will study the geometry and dynamics of neural network loss landscapes, including curvature, stochastic gradient noise, and the edge of stability.
Next, to gain insight into the training dynamics of deep networks, we will explore specific and insightful nonconvex toy problems. These are to be considered warm-ups (primitives) for deep learning problems. We will then examine training of standard deep neural networks and discuss the impact of initialization and (over)parametrization on optimization speed, feature learning, and generalization. We will discuss depth and the role of residual connections and normalization layers, eventually moving to Transformers. We will also discuss sharpness-aware minimization, implicit bias, the neural tangent kernel (NTK), and maximal update parametrization (muP), including how parametrization can enable hyperparameter transfer across model sizes.
Finally, we will discuss adaptive methods such as Adam and Muon, including momentum, preconditioning, their behavior on simple models, and their performance on Transformers and language models. We will connect these ideas to the practical ingredients behind training large models—architecture, parametrization, data, and optimization—and conclude with scaling laws, including simple theoretical arguments explaining why power-law behavior emerges with model size, data, and compute.
Requirements
The course requires some deep learning familiarity and basic knowledge of gradient-based optimization. Students who have already attended "Convex and Nonconvex Optimization" or any machine learning lecture that discusses gradient descent will have no problem following the lecture. In general, the semester requires good mathematical skills, roughly at the level of the lecture "Mathematics for Machine Learning." In particular, multivariate calculus and linear algebra are needed.
Exercises
Exercise sheets will be provided every week and the solutions will be provided. Exercises are not graded, and no project.
Exam
Written exam, 2h, closed book. Maybe let's do optional presentations. Let's decide together.
Schedule (Preliminary)
-
October 12 — Lecture 0
Intro + Linear Regression -
October 19 — Lecture 1
Gradient Descent on Quadratics, Curvature, Stepsizes. SignGD/Muon derivation -
October 26 — Lecture 2
Neural Nets Universality + Local Quadratic Dynamics - November 2 — Canceled
-
November 9 — Lecture 3
SGD Near Minima and Saddles + Kaiming Initialization -
November 16 — Lecture 4
Nonconvex Optimization: Smoothness, Descent Lemma, Convergence Rates -
November 23 — Lecture 5
Stochastic Nonconvex Optimization: Noise, Schedulers, Lower Bounds, PŁ. -
November 30 — Lecture 6
Generalization, L2 regularization optimality in regression, Sharpness-Aware Minimization, Double Descent, Benign Overfitting, Grokking -
December 7 — Lecture 7
Feature Learning, Neural Tangent Parametrization (NTK/NTP), maximal update parametrization (muP) -
December 14 — Lecture 8
Skip Connections, Hyper-Connections, Normalization Layers -
December 21 — Lecture 9
Pre/Post-LN in Transformers, Rank Collapse - December 28 — Break
- January 4 — Break
-
January 11 — Lecture 10
Adaptive optimizers. Convergence, basic properties, (L0,L1)-smoothness. -
January 18 — Lecture 11
Scaling Laws and hyperparameter transfer - January 25 — Canceled
- February 1 — Q/A + Exam Preparation